Ask five companies what a growth manager does and you will get five different answers. That ambiguity is harmless in conversation and expensive in a database. A well-built job title classification taxonomy turns messy free-text job titles into structured data your marketing, product and sales systems can actually use.
Without one, segmentation breaks quietly. Lead routing sends enterprise architects to the small business team. Personalization addresses a chief marketing officer as a practitioner. Reporting on audience composition becomes guesswork.
This guide covers how to design a taxonomy for digital, product, experience and marketing roles, how to implement it without a year-long project, and how to keep it accurate as titles keep evolving.
What Is a Job Title Classification Taxonomy?
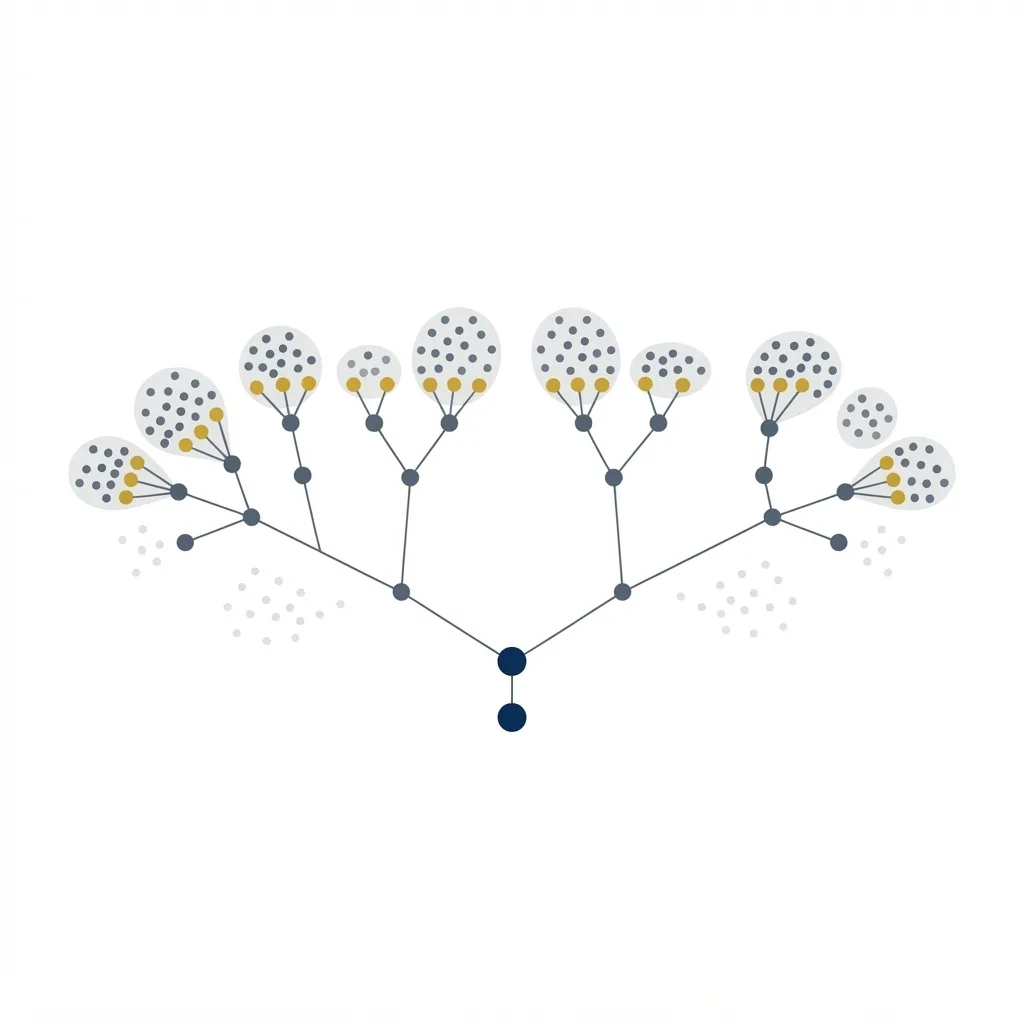
A job title classification taxonomy is a structured system that maps unlimited free-text job titles to a controlled set of standardized categories. Typically it captures several dimensions at once: function, seniority, specialization and sometimes department or scope.
For example, Senior Manager of Digital Customer Experience might resolve to function experience design, specialization customer experience, seniority manager, and scope digital. The taxonomy's job is to make a title machine-readable without losing the meaningful distinctions humans care about.
It is not an org chart and it is not a list of approved titles. It is a translation layer applied to data you do not control.
Who Needs One?
Any organization whose systems collect job titles from external people needs this more than they realize.
- B2B marketing teams segmenting campaigns by persona and seniority
- Product teams analyzing which roles actually use which features
- Sales operations routing leads and calculating territory fit
- Research and insights teams comparing survey responses across audiences
- Recruiting and talent analytics teams benchmarking market compensation
Core Design Dimensions
Function
The broad discipline the person works in: marketing, product management, engineering, design, data, operations. Keep this list short, usually under twenty entries, because granularity belongs in specialization rather than here.
Seniority
A normalized ladder such as individual contributor, senior individual contributor, manager, director, vice president and executive. Seniority is the single most predictive dimension for messaging, so invest disproportionate effort in getting it right.
Specialization
The specific focus within a function, for example demand generation, lifecycle marketing, design systems, growth product or analytics engineering. This layer changes fastest and needs regular review.
Confidence Score
Every classification should carry a confidence value. Titles like Ninja of Customer Delight should resolve with low confidence and be flagged, not silently forced into a bucket that corrupts your reporting.
How to Build and Implement It
Start from your actual data rather than designing an ideal schema in the abstract.
- Export every distinct job title in your database and count frequency for each.
- Identify the top titles covering roughly eighty percent of records; these deserve manual mapping.
- Define your dimension schema and lock the seniority ladder first.
- Write normalization rules for casing, punctuation, abbreviations and language variants.
- Apply rule-based matching first, then use a model for the unmatched long tail.
- Store the raw title alongside the classification so you can reclassify later without data loss.
- Review low-confidence outputs monthly and expand the rule set from what you find.
Benefits of Getting This Right
The payoff shows up across nearly every data-driven function.
- Accurate persona segmentation that makes campaign performance comparable over time
- Reliable lead routing that reduces handoff friction and response delays
- Meaningful product analytics showing which roles adopt which capabilities
- Cleaner account-based marketing through verified buying committee coverage
- Trustworthy executive reporting that survives scrutiny in board meetings
Potential Challenges
Taxonomy projects fail in predictable ways, usually from scope rather than technique.
- Over-engineering the schema until nobody can maintain or explain it
- Title inflation, where a startup director outranks nothing and an enterprise one manages eighty people
- Multilingual and regional variation that rule-based matching handles poorly
- Drift, as new role types appear faster than the taxonomy is reviewed
Best Practices and Tips
Keep the system deliberately small and rigorously maintained.
- Never overwrite the original title string; always classify into new fields
- Cap your top-level function list and resist requests to add narrow categories
- Combine seniority with company size, since titles mean different things at different scales
- Assign a single owner responsible for quarterly taxonomy reviews
Real-World Example
A digital experience platform had over eleven thousand unique job titles across two hundred thousand contacts. Their marketing team segmented by simple keyword matching, so anyone with marketing in their title received practitioner content, including chief marketing officers.
They built a three dimension taxonomy with confidence scoring. Rule-based matching resolved seventy-one percent of records immediately; a classification model handled most of the remainder, leaving about four percent flagged for manual review. Executive-targeted campaigns, previously buried in practitioner sends, were separated out and produced a meeting booking rate more than three times higher. Product analytics also revealed that designers, not marketers, were their heaviest feature users, which redirected the following year's roadmap.
Why It Matters
Marketing and product decisions are only as good as the segmentation underneath them. Job title is often the single richest attribute you collect, and it is almost always the messiest.
Investing in a job title classification taxonomy is unglamorous infrastructure work that quietly improves the accuracy of every downstream decision. Companies building this into their data layer often pair it with broader AI-powered data classification services to handle the long tail at scale.
Frequently Asked Questions
Should I build a taxonomy or buy an enrichment service?
Enrichment vendors provide a fast baseline, but their categories rarely match how your business segments customers. Most mature teams use vendor data as an input and maintain their own mapping layer on top.
How many categories should a taxonomy have?
Aim for fifteen to twenty functions, five to seven seniority levels and as many specializations as you can genuinely maintain. If a category has fewer than a hundred records, it probably should not exist separately.
How do I handle titles in other languages?
Normalize to a single working language during classification while preserving the original string. Maintain explicit translation rules for your highest-volume markets rather than relying on generic translation.
How often should the taxonomy be reviewed?
Quarterly for specializations, annually for functions and seniority. Review the unmatched and low-confidence queue monthly, since that is where emerging role types appear first.
Conclusion
A good taxonomy is small, well documented, confidence-aware and owned by someone specific. It will never be perfect, and it does not need to be; it needs to be consistently better than free-text guessing.
Start with your top titles, ship something usable, and improve it on a schedule. Teams needing help building the supporting data infrastructure can look at custom web application development to operationalize it.